The verified 8 GB entry point
768² with float16, certified on the Turing sm75 RTX 2060 SUPER 8 GB.
- ≥ 8 GB VRAM
- 768²
- float16
- No Z-Image Turbo
COMPATIBILITY
The standard tier uses 1024² with bfloat16; the compact tier uses 768² with float16. Background removal and upscaling use separate runtimes.
Generative models require a supported 8 GB NVIDIA GPU for the compact tier. A 12 GB GPU enables the standard tier; Z-Image Turbo still requires 12 GB. BiRefNet and Real-ESRGAN are outside this tier system.
768² with float16, certified on the Turing sm75 RTX 2060 SUPER 8 GB.
1024² with bfloat16, including the current certified generative models and Z-Image Turbo.
COMPATIBILITY
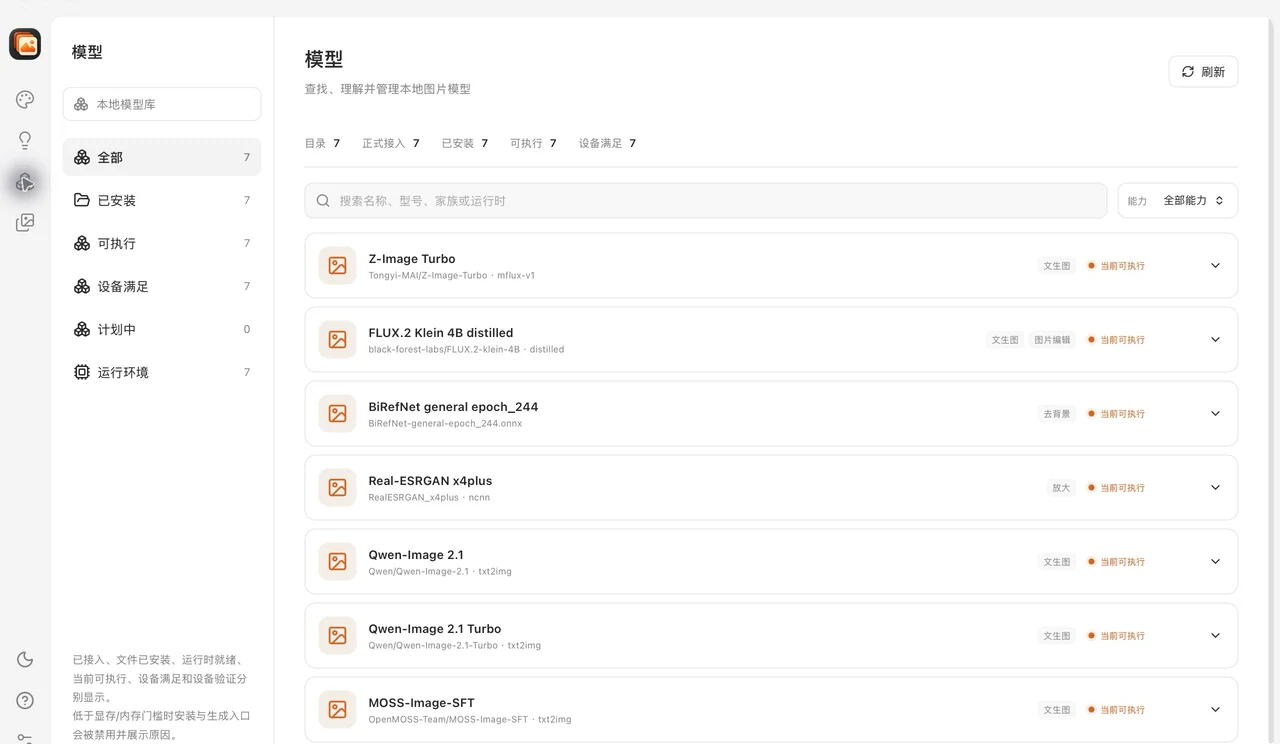
The app manages model identity, downloads, and runtimes; this table describes the certified scope only.
| Model | Capability | Hardware eligibility | Pinned recipe or runtime |
|---|---|---|---|
| Z-Image Turbo | Text to image | Standard tier only; 1:1, 4:3, 3:4 | Fixed 9-step recipe with 4-bit loading; not available on 8 GB GPUs. z-image-turbo |
| FLUX.2 Klein 4B distilled | Text to image / single-image edit | Standard and compact tiers | 4 steps with guidance 1.0, including reference-image editing. flux-klein-4b-distilled |
| BiRefNet general epoch_244 | Remove background | ONNX Runtime CPU | Returns transparent RGBA output plus a companion mask; not bound to the generative VRAM tiers. birefnet-general |
| Real-ESRGAN x4plus | Exact 4× upscale | ncnn Vulkan; tile 128 | Performs exact 4× upscaling and is not classified by the generative model VRAM tiers. real-esrgan-x4plus |
| Qwen-Image 2.1 | Text to image | Standard and compact tiers | Fixed 40-step recipe with 4-bit NF4 loading. qwen-image-2-1 |
| Qwen-Image 2.1 Turbo | Text to image | Standard and compact tiers | 8-step Turbo sampling for faster local generation. qwen-image-2-1-turbo |
| MOSS-Image-SFT | Text to image | Standard and compact tiers | Fixed 50-step recipe with 4-bit NF4 loading. moss-image-sft |
Text to image
Standard tier only; 1:1, 4:3, 3:4
Fixed 9-step recipe with 4-bit loading; not available on 8 GB GPUs.
Text to image / single-image edit
Standard and compact tiers
4 steps with guidance 1.0, including reference-image editing.
Remove background
ONNX Runtime CPU
Returns transparent RGBA output plus a companion mask; not bound to the generative VRAM tiers.
Exact 4× upscale
ncnn Vulkan; tile 128
Performs exact 4× upscaling and is not classified by the generative model VRAM tiers.
Text to image
Standard and compact tiers
Fixed 40-step recipe with 4-bit NF4 loading.
Text to image
Standard and compact tiers
8-step Turbo sampling for faster local generation.
Text to image
Standard and compact tiers
Fixed 50-step recipe with 4-bit NF4 loading.
Installers do not include model weights. Each generative model is about 25–33 GB; reserve roughly 40 GB per model.
Per generative model
Reserve per model
Full model set
Apple Silicon arm64 with macOS 11 or newer.
Windows 10 22H2 or Windows 11 x64 with a supported NVIDIA GPU.
Hardware and storage facts come from the pinned source, model catalog, and current verification records without extrapolation.